What an NPU Is and Why New Laptops and Phones Have One
A neural processing unit, or NPU, is a chip block built to run AI models efficiently. Here is what it does, how TOPS is measured and how it differs from a CPU or GPU.
In this article
A neural processing unit, or NPU, is a part of a chip designed to run artificial intelligence workloads quickly and with little power. It does one family of calculations, the matrix maths behind neural networks, rather than everything a processor might be asked to do. Phones have carried such blocks for years, and laptops now advertise them too. This article explains what an NPU does, what "TOPS" means on a spec sheet, and where an NPU fits next to the CPU and GPU.
What an NPU is
Wikipedia defines an NPU, also called an AI accelerator or deep learning processor, as a class of specialised hardware designed to speed up artificial intelligence and machine learning applications, including neural networks and computer vision. An NPU can be a separate chip, or a block inside a CPU or a graphics processor. Microsoft describes it as a specialised chip for AI-heavy tasks such as real-time translation and image generation.
The aim is usually inference, which means running an AI model that has already been trained. Training a large model takes far more hardware, usually in data centres. Running a small trained model, for example to blur a video call background, is the job an NPU in a laptop or phone is built for.
Why not just use the CPU or GPU?
A CPU is built for general work: running programs, making decisions, handling many different tasks. A GPU has many small units that do similar sums in parallel, which suits graphics and also AI. An NPU narrows the job further. Wikipedia says NPUs focus on low-precision arithmetic and are often designed with many cores and special data-flow layouts. Because they do less, they can use less energy for the same AI work.
Microsoft says the NPU on a Windows Copilot+ PC can process large amounts of data in parallel and use energy on AI tasks more efficiently than a CPU or GPU, which helps battery life. Windows decides which part of the chip should do each task, and the NPU needs software written to use it. An app that is not written for the NPU will not run faster just because the chip is present.
What low precision means
Computers store numbers with different amounts of detail. A scientific calculation may need many digits. Many trained AI models work well with far fewer. Wikipedia notes that consumer NPUs are designed for low-bitwidth operations using number types such as INT4, INT8, FP8 and FP16. Fewer bits per number means less data to move and smaller circuits, so more of the sums fit into the same space and power budget.
What TOPS means
The common speed rating for an NPU is TOPS, trillions of operations per second. Wikipedia explains that TOPS does not say exactly which kind of operation is counted, and that it is typically INT8 additions and multiplications. That means two chips with the same TOPS number can behave differently, and the figure should not be compared with a CPU's clock speed or a GPU's teraflops.
Microsoft sets a number for its own branding: it says many new Windows AI features need an NPU that can run at 40 or more TOPS, and it describes Copilot+ PCs as having an NPU that can perform more than 40 trillion operations per second. As of the version of Microsoft's page read for this article, the listed examples include chips from Qualcomm, AMD and Intel.
Where NPUs are found
- Phones: Wikipedia lists AI accelerators in Apple silicon, Qualcomm, Samsung, Huawei and Google Tensor phone processors
- Laptops: Wikipedia says NPUs were added to Intel processors from about 2022 and AMD processors, after Apple added one around 2017
- Data centres: Google's TPU and Amazon's Trainium and Inferentia chips are accelerators of a larger kind
- Vision devices: Wikipedia notes vision processing units are used in drones and augmented-reality headsets
How software reaches the NPU
Programs do not talk to an NPU directly. They use a framework such as Core ML on Apple devices, DirectML or Windows ML on Windows, or LiteRT on Android, which Wikipedia lists as ways to reach these chips. Microsoft says Windows ML detects the available hardware and downloads the matching components, so a developer does not need to bundle each vendor's code. Trained models are often shared in formats such as ONNX.
What to take from this
- An NPU runs trained AI models efficiently; it is not a faster general processor
- TOPS is a rough guide, and it counts a specific kind of low-precision operation
- Benefits depend on software written to use the NPU
- Cloud AI services still run on data-centre hardware, not on the NPU in a laptop
Sources
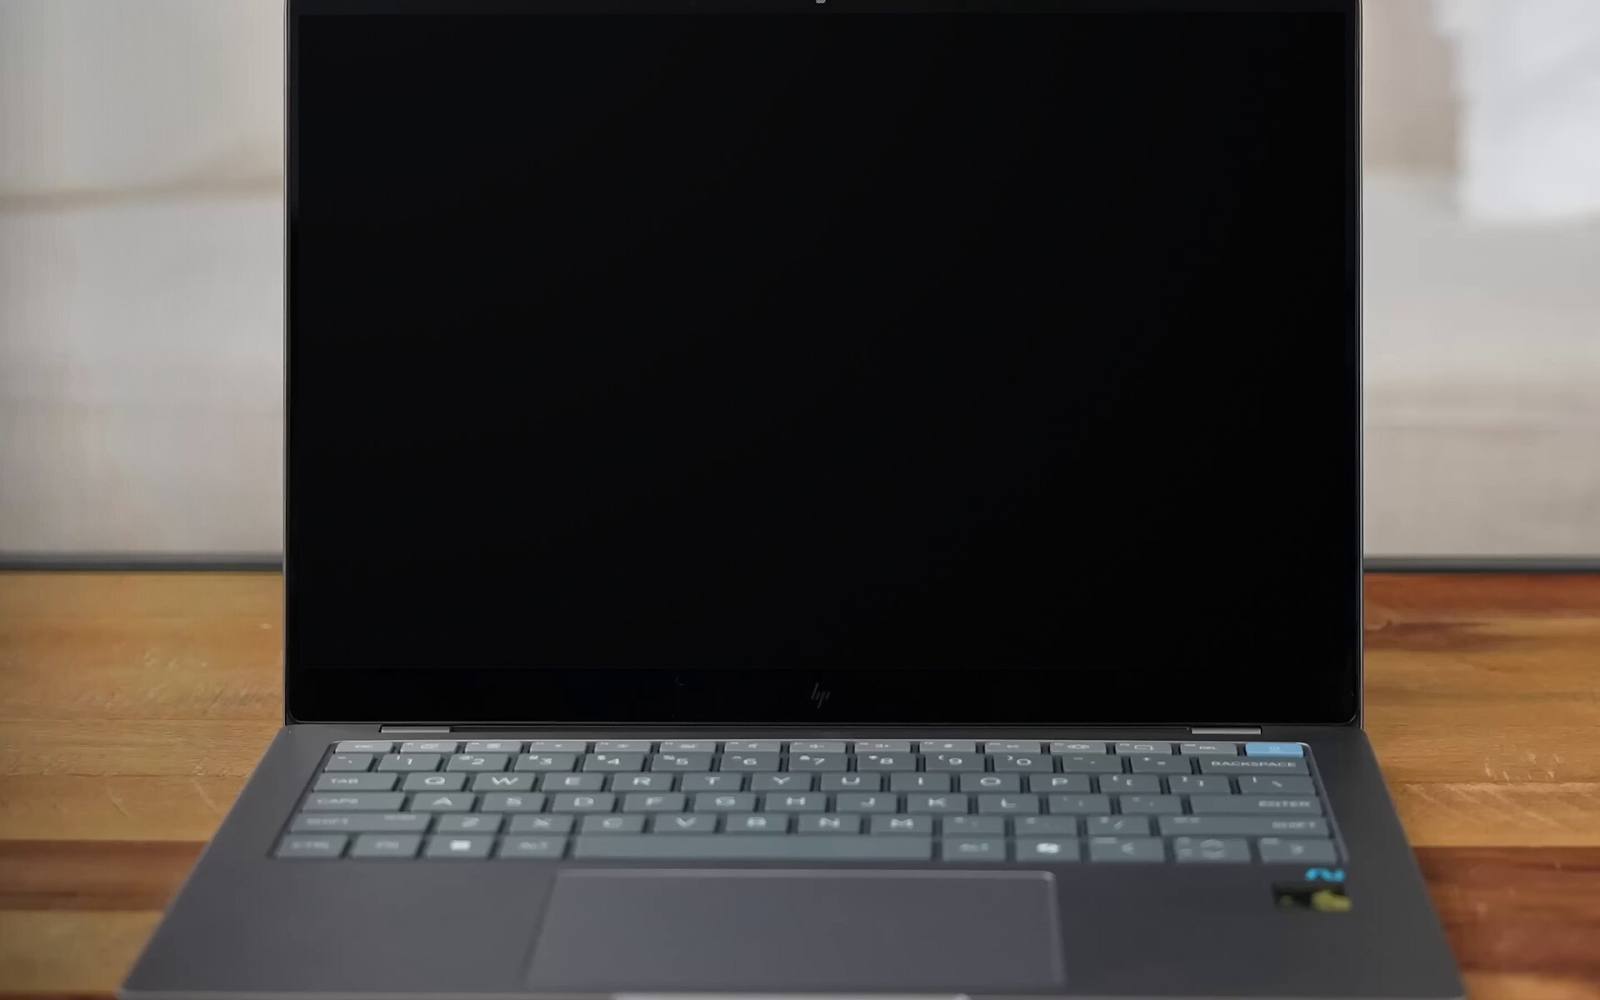
Image credits: Cover photo: HP OmniBook X by Booredatwork.com, CC BY 3.0. Pictures from Wikimedia Commons.

Share
Keep reading
Related articles
How Much Electricity Do AI Data Centres Use?
Data centres used about 1.5% of the world's electricity in 2024. Here is what the IEA and the US Department of Energy report, what drives the growth and how uncertain the forecasts are.
What Is a Context Window? Why AI Chatbots Forget Things
A context window is the amount of text an AI model can look at in one go. Learn what counts toward it, how tokens relate to words, and why long chats can lose track of earlier details.
How Email Travels: SMTP, MX Records, IMAP and POP3
Email passes through several programs and servers between sender and inbox. Here is the route, what MX records and SMTP do, and how IMAP differs from POP3.